10 posts tagged with "Announcement"

Releases, project milestones, and official announcements.

View All Tags

Announcing Apache Fluss 1.0: Real-Time Data Foundation for AI

Keith Lee
PMC member of Apache Fluss
Jark Wu
PMC Chair of Apache Fluss

Apache Fluss 1.0

🌊 We are excited to announce the official release of Apache Fluss 1.0!

AI agents and applications need data that keeps up with the world around them: current user profiles, recent interactions, changing business state, and fresh features for inference. Training pipelines also need access to historical data and newly arriving events. Fluss 1.0 strengthens the data layer connecting these workloads, from straightforward HTTP access for agents and native Python integration to continuous processing with Flink and training data preparation with Spark.

This is the first major release since Fluss graduated from the Apache Incubator to become a Top-Level Project. The community took a longer development cycle to prepare for this milestone. The release brings together over a thousand commits and 450,000 new lines of code, roughly three times the amount added in previous releases. These numbers reflect the breadth of feature development, refinement, and validation, as well as the Fluss community's continued collaboration and active development.
Apache Fluss Graduates to a Top Level Project

Jark Wu
PMC Chair of Apache Fluss

Apache Fluss Graduates to a Top Level Project

As officially announced by the Apache Software Foundation, we are thrilled to share that Apache Fluss has graduated from the Apache Incubator to become a Top Level Project (TLP).

The project's graduation proposal received unanimous approval from the Apache Incubator Project Management Committee (IPMC) and was subsequently approved by the ASF Board of Directors. This milestone not only marks a new stage in Fluss's journey, but also further advances the convergence of streaming storage, the real-time Lakehouse, and AI data infrastructure, opening a new chapter for real-time data infrastructure.

Announcing Apache Fluss (Incubating) Rust, Python, and C++ Client 0.1.0 Release

Luo Yuxia
PMC member of Apache Fluss
Keith Lee
PMC member of Apache Fluss
Anton Borisov
PMC member of Apache Fluss

Banner

We are excited to announce the release of fluss-rust clients 0.1.0, the first official release of the Rust, Python, and C++ clients for Apache Fluss. This 0.1.0 release represents the culmination of 210+ commits from the community, delivering a feature-rich multi-language client from the ground up.

Under the hood, all three clients share a single Rust core that handles protocol negotiation, batching, retries, and Apache Arrow-based data exchange, with thin language-specific bindings on top. This was a deliberate community decision to deliver native performance and feature parity across every language from day one.

Apache Fluss (Incubating) 0.9 Release Announcement

Giannis Polyzos
PMC member of Apache Fluss
Jark Wu
PMC Chair of Apache Fluss

Banner

🌊 We are excited to announce the official release of Apache Fluss (Incubating) 0.9!

This release marks a major milestone for the project. Fluss 0.9 significantly expands Fluss’s capabilities as a streaming storage system for real-time analytics, AI, and state-heavy streaming workloads, with a strong focus on:

  • Richer and more flexible data models
  • Safe, zero-downtime schema evolution
  • Storage-level optimizations (aggregations, CDC, formats)
  • Stronger operational guarantees and scalability
  • A more mature ecosystem and developer experience

Whether you’re building unified stream & lakehouse architectures, real-time analytics, feature/context stores, or long-running stateful pipelines, Fluss 0.9 introduces powerful new primitives that make these systems easier, safer, and more efficient to operate at scale.


TL;DR: What Fluss 0.9 Unlocks​

Features

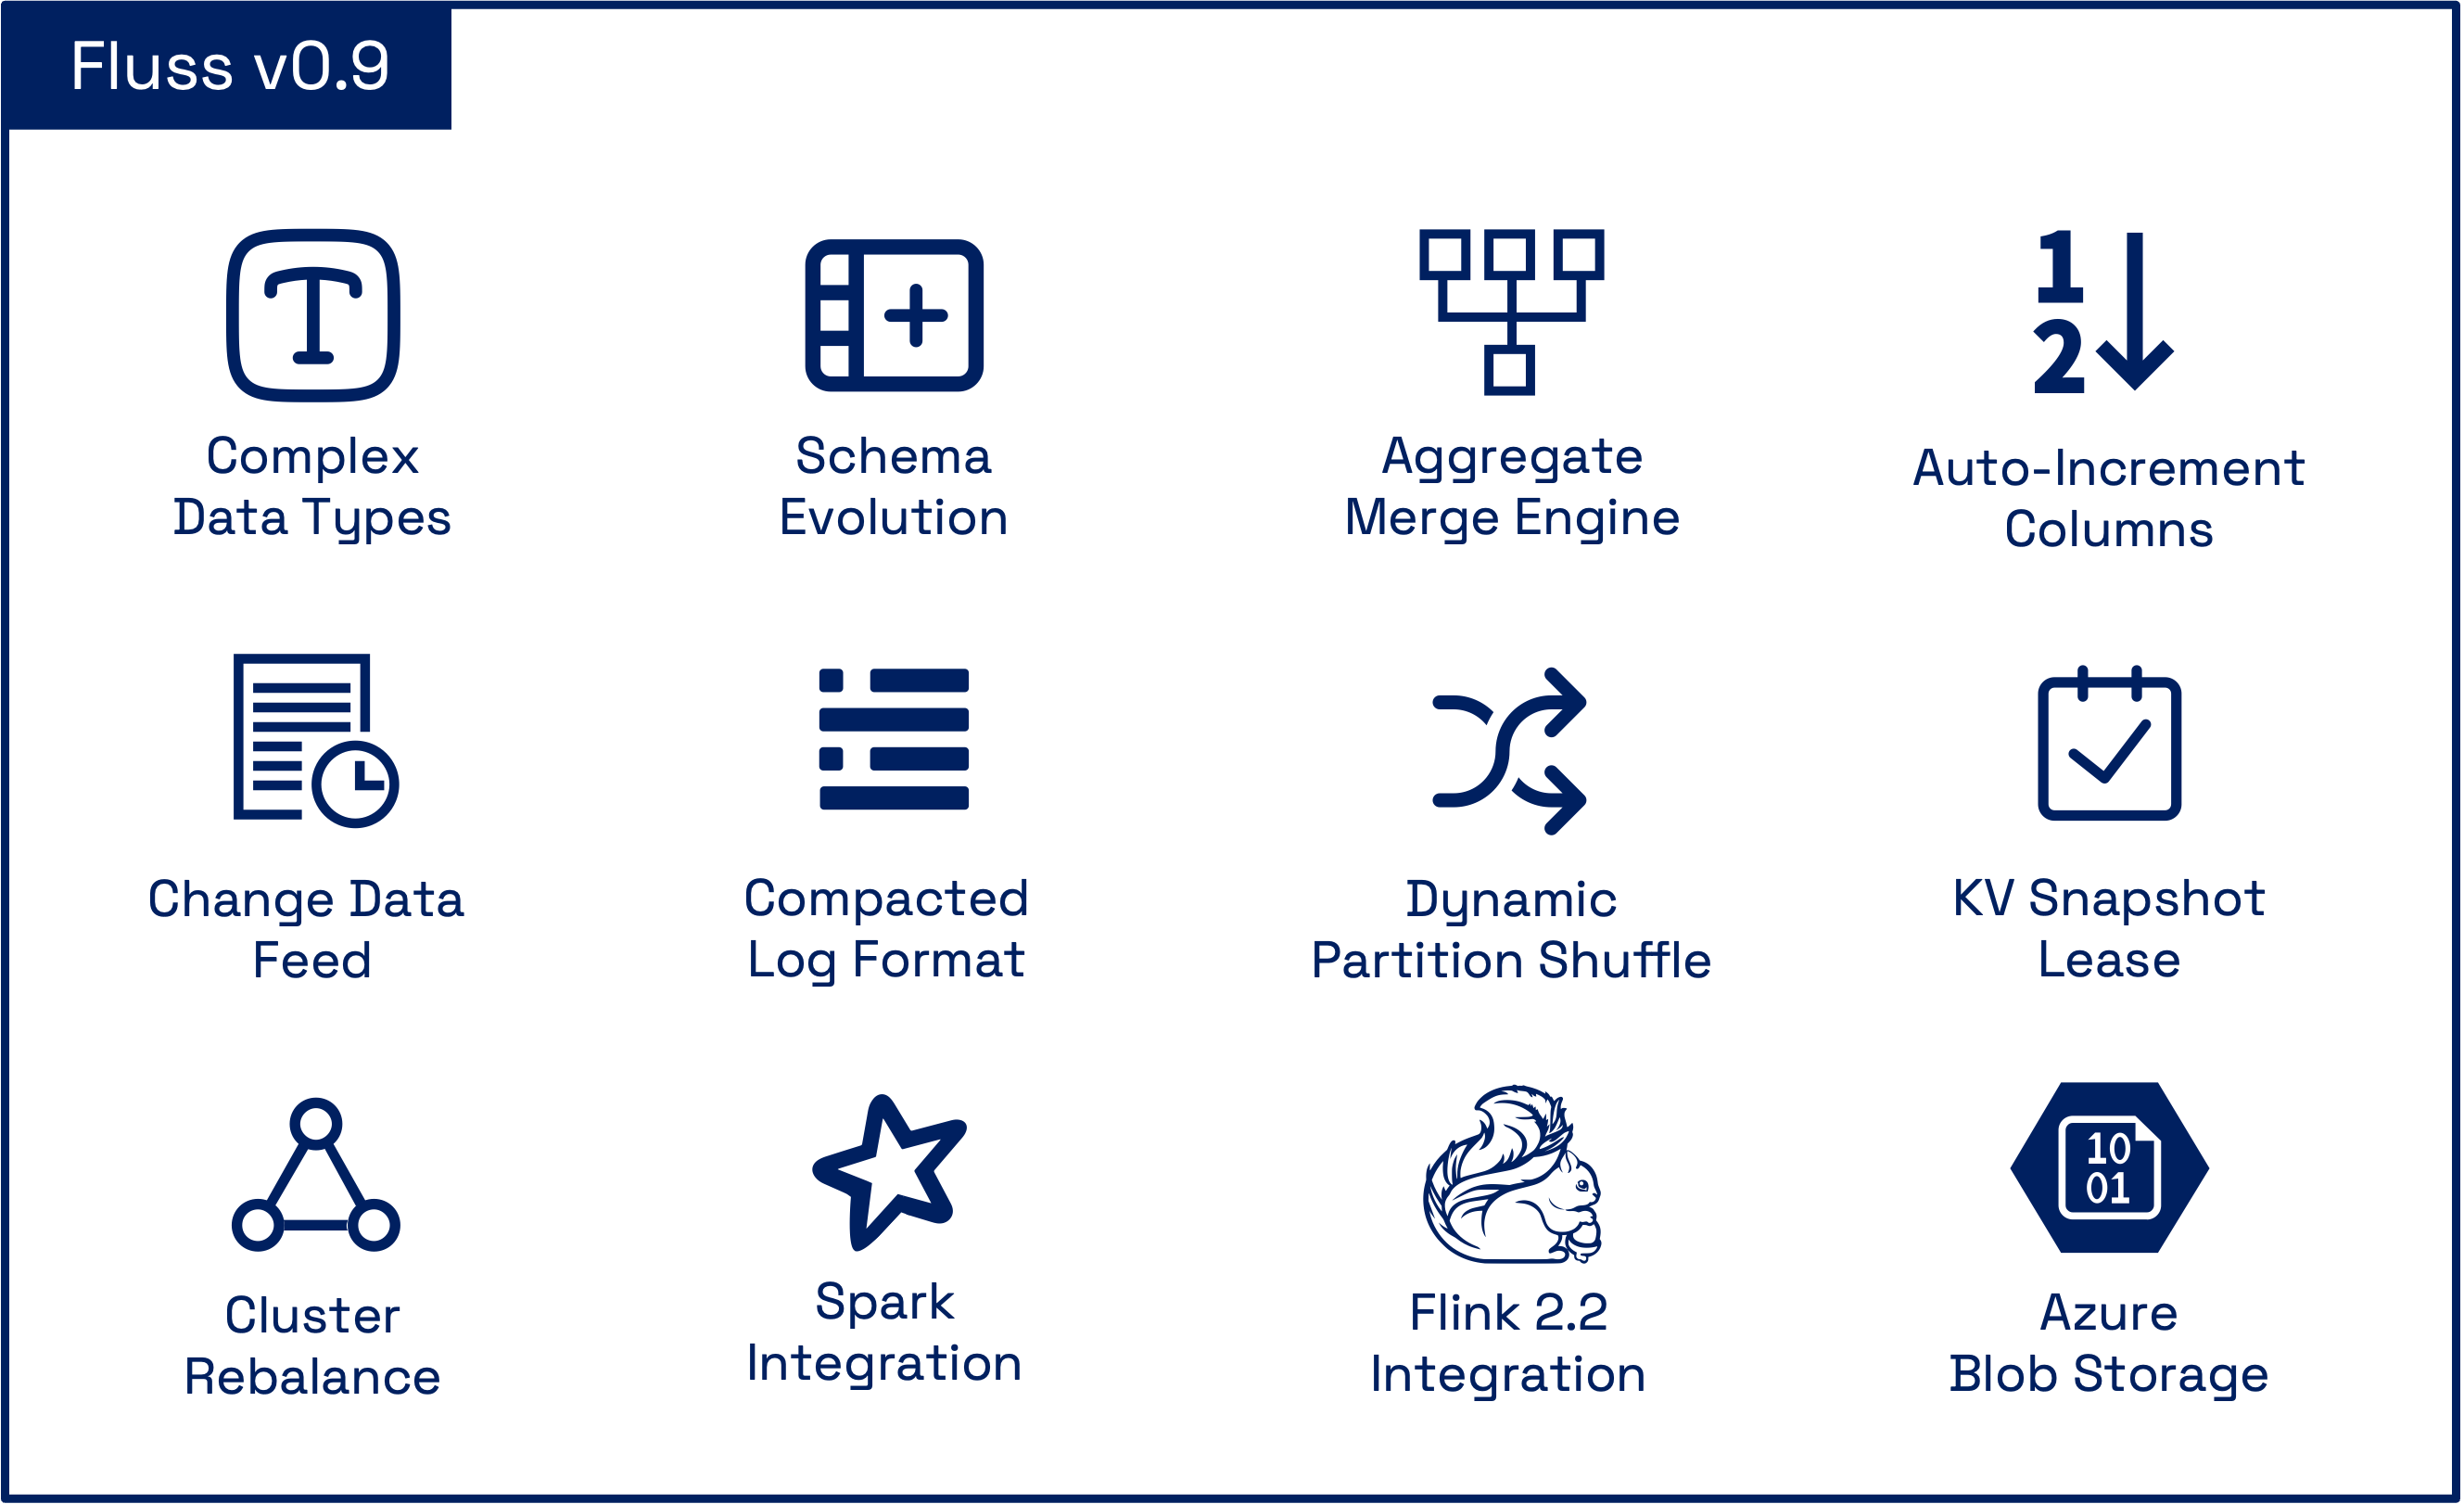
  • Zero-copy schema evolution for evolving streaming jobs
  • Storage-level aggregations that further enhances zero-state processing
  • Change data feed for CDC, audit trails, point-in-time recovery, and ML reproducibility
  • Safer snapshot-based reads with consumer-aware lifecycle management
  • Operationally robust clusters with automatic rebalancing and safer maintenance workflows
  • Apache Spark integration, enabling unified batch and streaming analytics on Fluss
  • First-class Azure support, allowing Fluss to tier and operate seamlessly on Azure Blob Storage and ADLS Gen2

Announcing Apache Fluss (Incubating) 0.8: Streaming Lakehouse for Data + AI

Giannis Polyzos
PMC member of Apache Fluss
Jark Wu
PMC Chair of Apache Fluss

Banner

🌊 We are excited to announce the official release of Apache Fluss (Incubating) 0.8!

This is our first release under the incubator of the Apache Software Foundation, marking a significant milestone in our journey to provide a robust streaming storage platform for real-time analytics.

Over the past four months, the community has made tremendous progress, delivering nearly 400 commits that push the boundaries of the Streaming Lakehouse ecosystem. This release includes multiple stability optimizations and introduces deeper integrations, performance breakthroughs, and next-generation stream processing capabilities. Highlights:

  • 🧊 Enhanced Streaming Lakehouse capabilities with full support for Apache Iceberg and Lance
  • ⚡ Introduction of Delta Joins with Flink, a game-changing innovation that redefines efficiency in stream processing by minimizing state and maximizing speed.
  • 🔧 Supports hot updates for both cluster configurations and table configurations

Apache Fluss 0.8 marks the beginning of a new era in streaming: real-time, unified, and zero-state, purpose-built to power the next generation of data platforms with low-latency performance, scalability, and architectural simplicity.

Fluss Joins the Apache Incubator

Jark Wu
PMC Chair of Apache Fluss

On June 5th, Fluss, the next-generation streaming storage project open-sourced and donated by Alibaba, successfully passed the vote and officially became an incubator project of the Apache Software Foundation (ASF). This marks a significant milestone in the development of the Fluss community, symbolizing that the project has entered a new phase that is more open, neutral, and standardized. Moving forward, Fluss will leverage the ASF ecosystem to accelerate the building of a global developer community, continuously driving innovation and adoption of next-generation real-time data infrastructure.

ASF

Announcing Fluss 0.7

Jark Wu
PMC Chair of Apache Fluss

Banner

🌊 We are excited to announce the official release of Fluss 0.7!

This version has undergone extensive improvements in stability, architecture, performance optimization, and security, further enhancing its readiness for production environments. Over the past three months, we have completed more than 250 commits, making this release a significant milestone toward becoming a mature, production-grade streaming storage platform.

The Story of Fluss Logo

Jark Wu
PMC Chair of Apache Fluss

Introducing the Little Otter​

Today is World Otter Day, and we are thrilled to introduce the little otter to the Fluss community! 🎉

Since open-sourced half a year ago, many community members and friends have asked us: "When will Fluss get a logo?" After more than a month of careful design work and over 30 iterations, we’re excited to finally unveil the official Fluss logo — a surfing otter! 🦦🌊

Announcing Fluss 0.6

Jark Wu
PMC Chair of Apache Fluss

The Fluss community is pleased to announce the official release of Fluss 0.6.0. This version has undergone over three months of intensive development, bringing together the expertise and efforts of 45 contributors worldwide, with more than 200 code commits completed. Our heartfelt thanks go out to every contributor for their invaluable support!

Release Announcement

Fluss is Now Open Source

Jark Wu
PMC Chair of Apache Fluss
Giannis Polyzos
PMC member of Apache Fluss

Earlier this year at Flink Forward 2024 Berlin we announced Fluss and today we are thrilled to announce open-sourcing the project. Fluss is a streaming storage system designed to power real-time analytics. It aspires to change how organizations approach real-time data by acting as the real-time data layer for the Lakehouse. Its cutting-edge design enables businesses to achieve sub-second latency, high throughput, and cost efficiency for data analytics, making it the ideal solution for modern data-driven applications.

We have historically invested a lot of effort into advancing the data streaming ecosystem, being major contributors to Apache Flink®, Apache Flink CDC, and Apache Paimon. As part of our commitment, Fluss is now open source under the Apache 2.0 license and is available on GitHub, inviting users to create the next generation of real-time architectures.

FF Announcement