The Streamhouse And Lakestream With Apache Fluss
Shared tables for streaming, serving and analytics
Engineering, ideas, and stories from the streaming frontier.
Shared tables for streaming, serving and analytics
31 articles
Fluss 1.0 strengthens the real-time data foundation for AI with Fluss Gateway, native clients, and deeper streaming and lakehouse integration.
A production case study in columnar streaming, cold-data isolation, and lakehouse integration.
Apache Fluss graduates to a Top-Level Project, marking a milestone in community growth and the evolution of real-time Lakehouse infrastructure.
Run lake tiering in production: identify failure modes, avoid deployment pitfalls, and monitor the signals that reveal operational health.
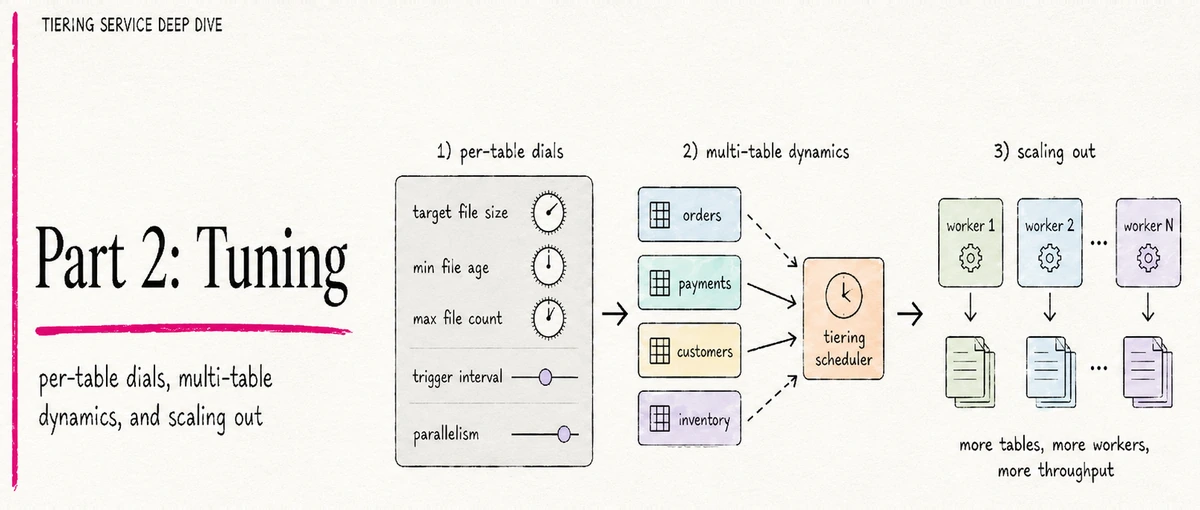
Tune lake tiering with a practical guide to parallelism, table types, freshness, multi-table scheduling, and scaling out tiering jobs.
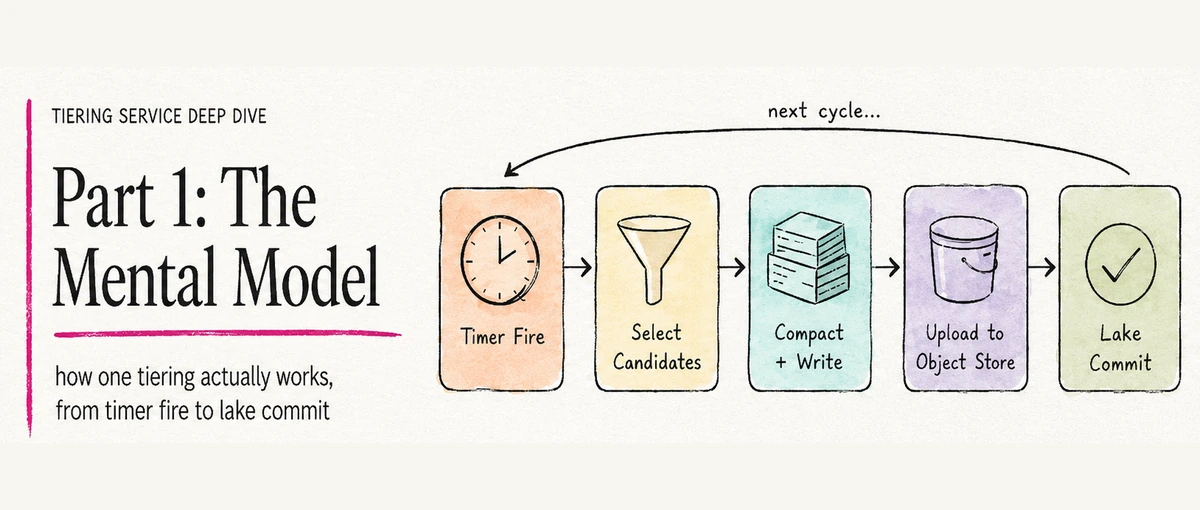
Follow a lake-tiering round from its timer to the committed snapshot, and understand the processes and table states that make it work.
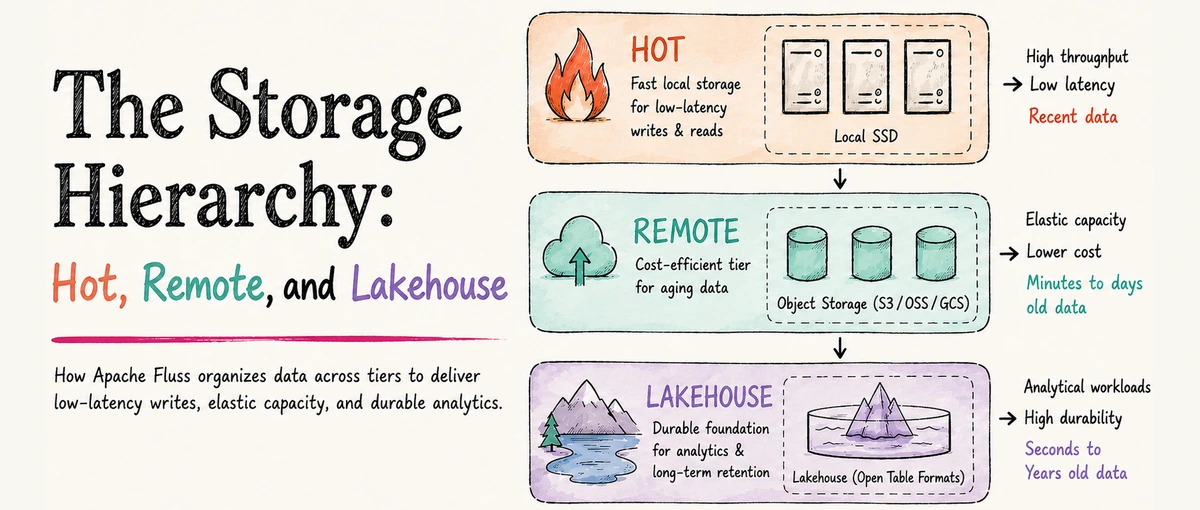
Understand the Fluss storage hierarchy: what lives on local disk, in remote object storage, and in the Lakehouse, and how recovery works.
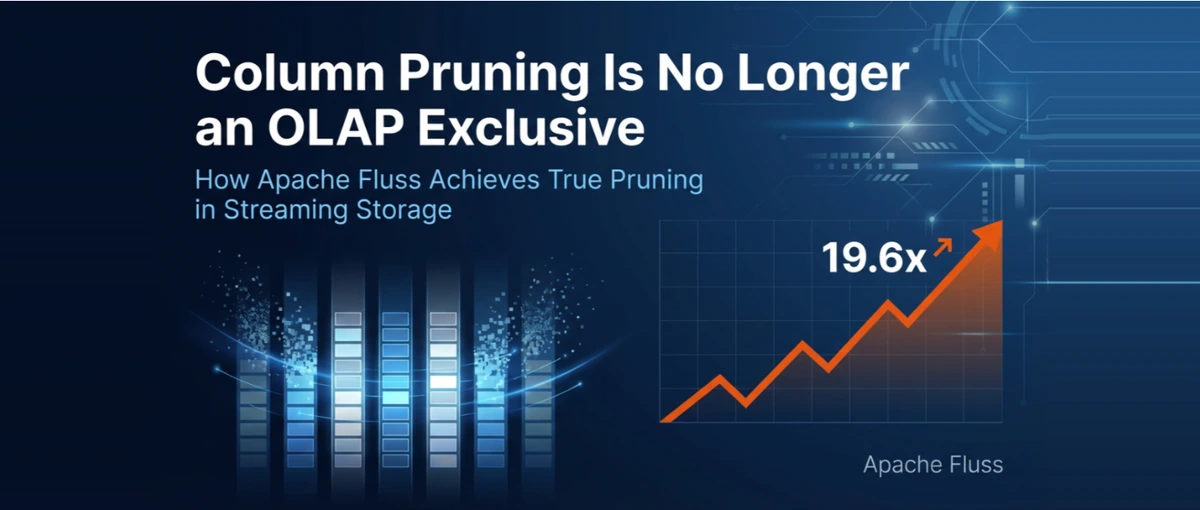
How Arrow IPC storage, server-side pruning, and client-side batching let Fluss read only the columns that streaming applications need.
How Taobao Instant Commerce uses Fluss for real-time decisions, from Delta Join and partial updates to lakehouse integration and UV statistics.